




Interviews
10 Operating System Interview Questions
Prepare with 10 operating system interview questions covering processes, memory, concurrency, file systems, model answers, and study resources.
Interview Pilot Editorial Team
Updated September 24, 2026
24 min read
You're in a technical interview, and the interviewer asks a deceptively simple question: “What's the difference between a process and a thread?” A definition alone won't carry the answer. You also need to explain what the operating system does, what changes during execution, where the trade-offs appear, and why the distinction matters for the role you want.
This guide builds an operating system interview questions map in a deliberate order. You'll move from execution and privilege boundaries through CPU scheduling, virtual memory, networking, concurrency, synchronization, deadlocks, and persistent storage. Each answer follows a practical framework: define the mechanism, trace a concrete example, state a trade-off, and connect the concept to a target role.
Use the workflow actively. Answer from memory, draw or trace the mechanism, compare alternatives, and rehearse the explanation aloud. For structured practice, you can use Interview Pilot's AI Mock Interview sessions or its Question Bank. If your wider preparation includes robotics or embedded systems, understanding what ROS is for teams can also help you connect operating-system fundamentals to real software environments.
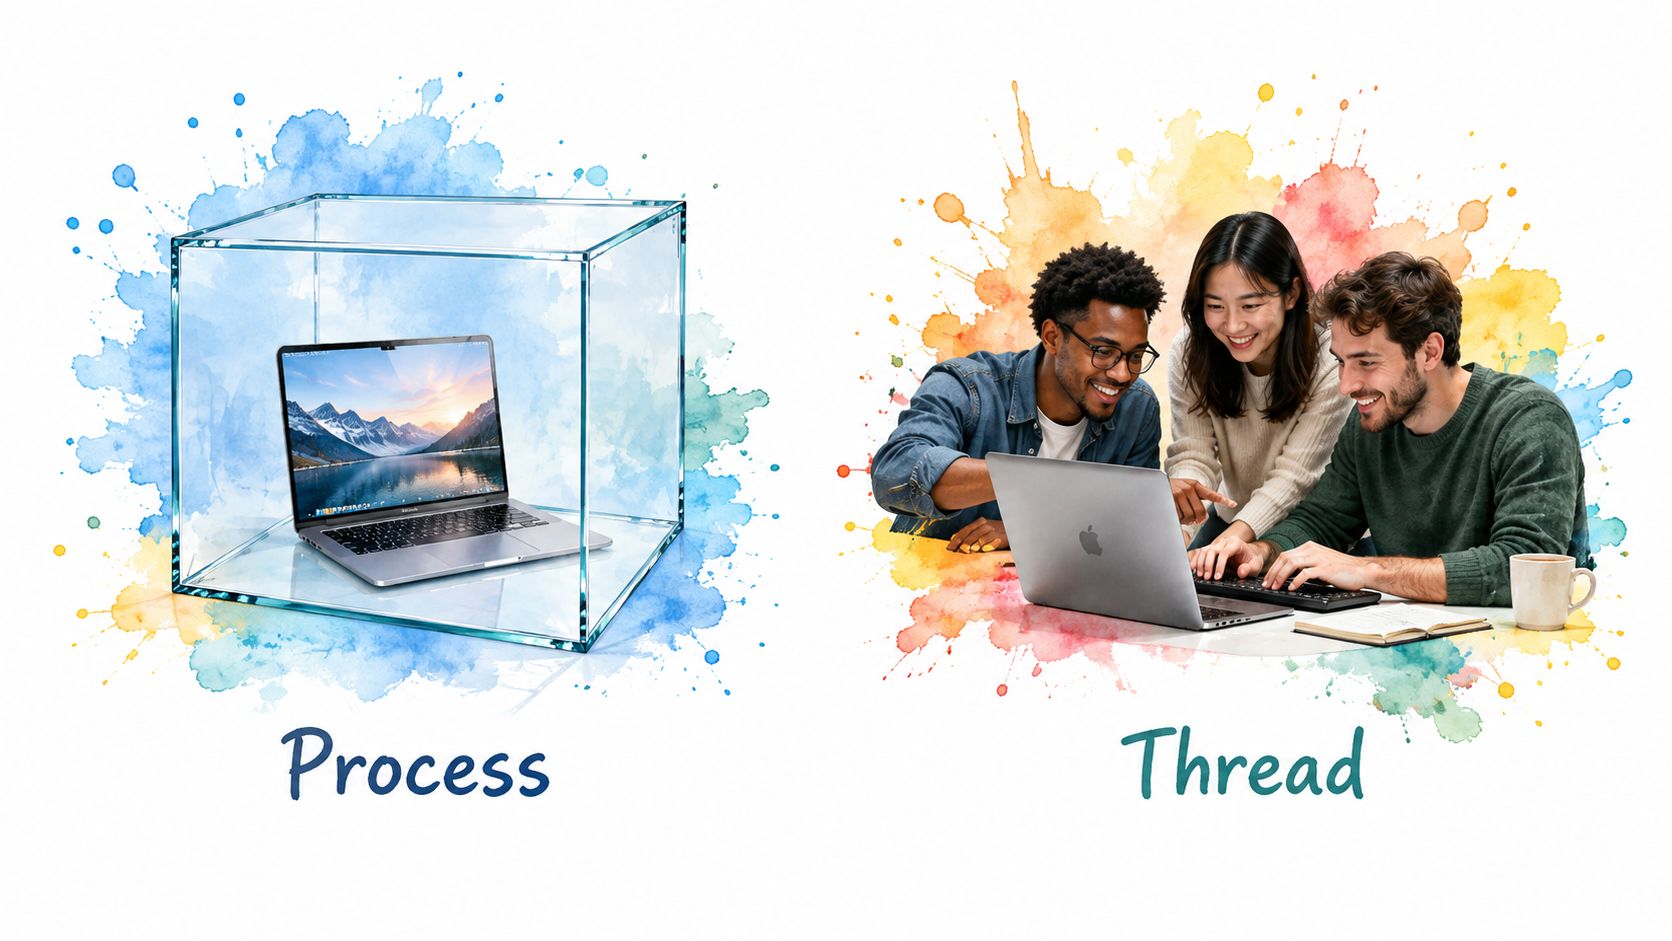
1. What is the difference between a process and a thread?
A process is a running program with its own virtual address space and operating-system resources. A thread is an execution path inside a process. Threads in the same process share code, heap memory, and open resources, while each thread maintains its own stack, registers, and execution state.
That distinction creates the central trade-off. Processes provide stronger isolation, so a memory error in one process is less likely to overwrite another process's data. Threads are generally lighter to create and communicate through shared memory, but shared state creates synchronization risks. A web server might use separate worker processes for isolation, a thread pool for lower-overhead request handling, or asynchronous functions to manage many waiting operations within a process.
A strong answer framework
Start with the definition, then compare memory ownership, communication, failure isolation, and scheduling. Explain that two Java processes usually run in separate JVMs with separate heaps, while Java threads inside one JVM share the heap. For Python, mention that the Global Interpreter Lock can limit parallel execution of Python bytecode, which makes process-based parallelism relevant for some CPU-bound workloads.
Practical rule: Don't describe threads as “mini-processes” without explaining shared memory. The shared address space is the reason threads communicate efficiently and the reason data races can occur.
Finish with the role connection. Backend candidates can discuss thread pools and request isolation. Systems candidates can explain context switching and resource ownership. Embedded candidates can compare task isolation with the constraints of a real-time environment. Before the interview, sketch one process containing several threads, then annotate which resources are shared and which are private. You can also improve focus by stopping background apps while studying so your tracing exercise reflects the system you're trying to understand.
2. What is a system call and how does it transition from user mode to kernel mode?
A system call is a controlled interface through which a user program requests a service from the operating system. Applications use system calls for operations such as opening files, reading data, creating processes, mapping memory, and sending network data. A library function may hide the call, but the program eventually crosses into privileged kernel code when it needs protected resources.
Consider read(). The application supplies a file descriptor and a buffer. A trap instruction transfers control to the kernel, the processor changes privilege state, and the kernel saves enough execution context to handle the request. The kernel validates the arguments and permissions, obtains the data from a cache or storage device, and returns a result to user mode.
Trace the boundary precisely
A good answer names the system-call number, the dispatch mechanism, register preservation, and the return path. The kernel uses the call identifier to select the correct handler. The transition itself has cost because the processor changes execution context, and the requested operation may trigger additional work such as scheduling, device access, or memory management.
That's why applications often buffer I/O rather than issue a separate call for every small piece of data. A program that repeatedly calls write() for tiny fragments can spend more time crossing the boundary than moving useful data.
For a Linux-focused preparation path, review Linux interview questions and troubleshooting topics. Then practice explaining how open(), read(), write(), fork(), exec(), and mmap() differ. Container-focused candidates can add seccomp to the discussion, because filtering system calls illustrates how the kernel boundary also supports security controls.
3. Describe different CPU scheduling algorithms and their trade-offs
CPU scheduling decides which ready task runs next. The interviewer usually wants more than a list of algorithms. You should show how each policy changes fairness, response time, waiting time, turnaround time, throughput, and context-switching overhead.
First-Come, First-Served runs tasks in arrival order. It's simple, but a long CPU-bound task can make short interactive tasks wait. Shortest Job First favors the task with the smallest expected CPU burst and can reduce average waiting time, but the operating system usually can't know the exact future burst. Priority scheduling serves higher-priority tasks first, yet lower-priority work can starve unless the system ages waiting tasks.
Round Robin gives each runnable task a time slice before moving to the next. It supports responsiveness and fairness, although very short time slices create more context switching. A multilevel feedback queue changes a task's priority based on observed behavior, often favoring interactive work while allowing longer jobs to progress.
Show the decision, not just the name
Draw a small Gantt chart. Place a long job ahead of several short jobs, then compare FCFS with Round Robin. State which metric improves and what the policy sacrifices. For real-time work, explain that meeting deadlines may matter more than maximizing average throughput. For Linux discussions, distinguish the general idea of fair allocation from implementation details of the current scheduler.
Your role should shape the example. A backend engineer can discuss latency for web requests. A batch-processing engineer can focus on throughput and turnaround. An embedded candidate should connect priority, deadlines, and priority inversion to the target system. The embedded systems interview questions guide can help you adapt the example to resource-constrained or timing-sensitive work.
A polished response names the workload first. Scheduling policies make sense only relative to the workload they serve.
Before studying, choose several tasks with different arrival times and burst lengths. Calculate the order by hand, then explain why the result changes when the time slice or priority policy changes.
4. What is virtual memory and how does paging or segmentation work?
Virtual memory gives each process an address space that the operating system maps onto physical memory. The process uses virtual addresses, while the memory-management unit translates them into physical frames. This abstraction supports process isolation, flexible allocation, and programs whose active working set doesn't fit entirely in RAM.
With paging, the virtual address divides into a page number and an offset. The page number indexes a page table, which identifies a physical frame. The offset selects the location within that frame. A translation lookaside buffer, or TLB, caches recent translations so the processor doesn't need to walk the page table for every access.
A page fault occurs when a referenced page isn't currently available in the expected physical-memory state. The kernel may load it from storage, allocate a new page, or reject the access if the address is invalid. Excessive page movement causes thrashing, where the system spends its effort servicing memory activity instead of running useful application code.
Compare paging with segmentation
Segmentation divides an address space into logical variable-sized regions, such as code, data, and stack. It can reflect program structure clearly, but variable-sized allocation can create external fragmentation. Paging avoids that form of fragmentation by using fixed-size units, although page tables and translation overhead consume memory.
A strong interview answer traces one address from virtual page to physical frame, then explains a TLB hit, a TLB miss, and a page fault. Discuss replacement strategies such as FIFO, LRU, Clock, and the theoretical optimal policy, but focus on the trade-off between implementation cost and approximation quality. Java heaps, database buffer pools, and invalid pointer accesses all provide useful scenarios.
Watch a visual explanation after you've drawn your own translation flow:
5. Explain the OSI model and network layers with examples
The OSI model organizes network communication into layers. Its value in an interview isn't memorizing a phrase. It's showing how a packet moves through different responsibilities and how you'd narrow down a failure.
From the bottom upward, the layers are Physical, Data Link, Network, Transport, Session, Presentation, and Application. Ethernet cables and Wi-Fi radio transmission belong to the Physical layer. MAC addresses and Ethernet frames belong to the Data Link layer. IP addressing and routing belong to the Network layer. TCP and UDP operate at the Transport layer, while HTTP, HTTPS, DNS, and SSH are commonly discussed at the Application layer.
Use encapsulation to explain the flow
When an application sends an HTTP request, the data moves down the stack. Each relevant layer adds control information, such as a transport header or an IP header. At the receiver, the layers remove and interpret those headers in reverse order. The operating-system network stack commonly handles lower-level functions, while applications interact through sockets and application protocols.
A practical explanation maps symptoms to layers:
- No link: Check the physical connection or wireless association before investigating application code.
- No route: Inspect IP configuration, routing, or ICMP behavior.
- Connection failure: Examine TCP handshakes, ports, firewalls, and timeouts.
- Application error: Inspect HTTP status, DNS behavior, authentication, or payload handling.
Tools make the answer concrete. tcpdump helps capture traffic from the host, and Wireshark helps inspect headers and exchanges. For a distributed-systems role, connect latency, retransmission, buffering, and throughput to the layer where each behavior appears. Don't claim that every layer maps cleanly to one software component. Real stacks combine and abstract layers, so explain the model as a debugging framework rather than a rigid implementation diagram.
6. What is a race condition and how do you prevent it?
A race condition occurs when the result depends on the timing or interleaving of concurrent operations. A data race is a narrower case involving unsynchronized access to shared data, where at least one access writes. Both ideas matter because a program can appear correct during ordinary testing and fail under a different schedule.
Take a shared counter. Two threads may both read the same value, increment their private copy, and write back the same result. The operation looks like one statement in source code, but it contains multiple machine-level actions. Without atomicity or synchronization, one update can overwrite the other.
Start with the shared state
A clear response identifies the resource, names every concurrent accessor, and lists the interleaving that creates the bug. Then compare prevention strategies:
- Mutex protection: Guard the entire read-modify-write sequence with exclusive access.
- Atomic operations: Use an atomic increment when the operation fits the available primitive.
- Immutability: Keep shared values unchanged and create new values instead.
- Message passing: Transfer ownership or send work rather than sharing mutable state.
- Thread-safe structures: Use a collection whose operations provide the required synchronization.
Visibility also matters. A lock can establish a happens-before relationship, while a poorly designed double-checked initialization pattern may observe stale or incompletely published state. A check-then-act sequence creates a similar risk when the checked condition can change before the action.
A web service might race while updating an in-memory cache. A database transaction might lose an update if concurrent writes don't use an appropriate isolation or locking strategy. In an interview, state the correctness requirement before choosing the mechanism. Then mention the cost, because stronger synchronization can reduce concurrency and increase contention. For practice, inspect a short code sample and narrate two possible thread interleavings aloud.
7. Explain process synchronization primitives and their use cases
Synchronization primitives coordinate access to shared state or coordinate progress between execution units. The important distinction is semantic, not just syntactic. A mutex protects exclusive ownership, a semaphore represents available permits or signals, a condition variable lets a thread sleep until a predicate may be true, and a read-write lock separates shared reads from exclusive writes.
A mutex fits a critical section such as updating a linked list. A condition variable fits a producer-consumer queue: consumers sleep when the queue is empty, and producers signal after adding work. The waiting thread must check the predicate in a loop because waking up doesn't guarantee that the condition still holds.
Explain why blocking beats busy-waiting
A spin lock repeatedly checks whether a lock is available. That can make sense when the critical section is extremely short and the expected wait is shorter than the cost of blocking, but it wastes CPU time during longer waits. A blocking mutex lets the scheduler run other work.
A read-write lock can help when many threads read stable data and writes are infrequent. Its trade-off is complexity and possible writer or reader starvation, depending on fairness policy. A barrier serves another purpose: it holds participating threads until they all reach a checkpoint.
Correctness comes before cleverness. A fast primitive that protects the wrong state still produces a broken program.
Use the monitor pattern as a practical synthesis. An object owns its data, a mutex protects access, and condition variables coordinate state changes. For Java candidates, compare these concepts with synchronized, ReentrantLock, Condition, and concurrent collections. The Java programming interview questions resource can help you rehearse that mapping. Your study action is to take one bounded queue and choose a primitive for each operation, then explain why the alternatives are less suitable.
8. What is a semaphore and how does it differ from a mutex?
A semaphore is a counter used to control access or signal progress. A thread performs a wait operation to acquire a permit. If no permit is available, it waits. A signal operation returns a permit or wakes a waiting participant. A counting semaphore can represent a pool of identical resources, while a binary semaphore has only two states.
A mutex is an ownership-based mutual-exclusion mechanism. One thread locks it, enters the critical section, and releases it when finished. The ownership rule matters because it helps define who may release the lock and supports debugging and correctness guarantees in many implementations.
Use a resource-pool example
Suppose a service has a limited set of database connections. A counting semaphore initialized to the number of available connections lets that many tasks proceed. Each task waits before borrowing a connection and signals after returning it. The semaphore limits concurrency without requiring one exclusive lock around the entire operation.
A mutex would be appropriate for protecting the pool's internal bookkeeping, such as a queue of available connections. The semaphore controls capacity, while the mutex protects shared metadata. That distinction is the answer interviewers want.
Semaphores can also coordinate producer-consumer behavior. One semaphore can count available items, another can count free slots, and a mutex can protect the queue itself. Don't imply that a binary semaphore and a mutex are interchangeable in every design. Their APIs, ownership semantics, priority behavior, and intended use can differ by operating system.
Your response framework should define each primitive, show the wait and signal sequence, and state the failure risk. Forgetting to signal can block future work. Holding a mutex while performing slow I/O can create contention. Study by drawing a resource pool with permits, then explain why a mutex alone doesn't express the number of resources available.
9. Explain the concept of deadlock and how to prevent it
A deadlock occurs when multiple processes or threads wait indefinitely because each holds a resource that another needs. A classic example uses two mutexes. Thread A acquires the first and waits for the second, while Thread B acquires the second and waits for the first. Neither can continue or release its held resource.
The standard analysis identifies four necessary conditions: mutual exclusion, hold and wait, no preemption, and circular wait. Deadlock prevention removes at least one condition. A global lock-ordering rule attacks circular wait. A design that acquires all required resources before proceeding attacks hold and wait, although it can reduce flexibility or resource utilization.
Separate prevention, avoidance, and detection
Prevention changes the design so deadlock cannot form under the stated rules. Avoidance evaluates whether granting a request could leave the system unsafe, as in the banker's algorithm. Detection allows deadlock to occur and searches for cycles, after which the system chooses recovery actions.
Practical measures include consistent lock ordering, narrow critical sections, lock timeouts, cancellation, and resource ownership protocols. A database team might impose a table-lock order. A multithreaded service might use a single composite lock or a lock-free data structure for a hot path. A distributed system adds network waits and service dependencies, so a cycle can cross process boundaries.
Don't confuse deadlock with livelock, where participants remain active but make no progress, or starvation, where one participant waits while others continue. In an interview, draw a resource-allocation graph and mark ownership and requests. Then explain the trade-off: strict ordering can prevent deadlock, but it may constrain how code composes operations. Test your answer with a banking example in which two transfers acquire account locks in opposite orders.
10. Describe file-system architecture and inode-based storage
An inode stores metadata about a file, such as permissions, ownership, timestamps, size, and pointers to data blocks. A directory is a mapping from names to inode references. This separation lets several directory entries refer to the same underlying file metadata, which is why hard links can share an inode.
Path lookup follows directory components. The operating system resolves a directory name, obtains the referenced inode, and continues until it reaches the requested file. The inode then identifies the blocks containing the file's content. Direct pointers handle smaller files efficiently, while indirect pointer structures extend the addressable size for larger files.
Include links, allocation, and recovery
A hard link creates another name for the same inode. A symbolic link stores a path reference instead, so it can point across file systems or refer to a target that later moves or disappears. The inode link count helps the file system track how many directory entries reference the inode.
Free-space tracking may use bitmaps or free lists. Allocation choices affect fragmentation and lookup cost. Sparse files add another useful scenario: a file can contain logical holes without allocating physical blocks for every unused region.
Journaling improves crash recovery by recording selected metadata or operations before applying them to the main structures. After an unclean shutdown, the system can use the journal to restore consistency, although journaling doesn't guarantee that application data was written in the order the application expected.
For a strong answer, trace open() from a path lookup to a file descriptor, then explain how read() follows inode pointers. Compare metadata overhead with file size, and mention that file systems impose limits related to blocks, inodes, path resolution, and maximum file size. As a study action, draw two hard links and one symbolic link, then show which inode each name reaches.
OS Interview Topics: 10-Point Comparison
| Topic | 🔄 Implementation complexity | ⚡ Resource requirements | 📊 Expected outcomes | 💡 Ideal use cases | ⭐ Key advantages |
|---|---|---|---|---|---|
| What is the difference between a process and a thread? | Medium, conceptual clarity; OS specifics add depth | Processes: high memory/overhead; Threads: lightweight ⚡ | Clear distinction of isolation vs shared state; informs concurrency design 📊 | Backend systems, multithreaded apps, systems programming 💡 | Foundational for concurrency and performance tuning ⭐ |
| What is a system call and how does it transition from user mode to kernel mode? | High, requires CPU/arch and privilege knowledge 🔄 | Low runtime footprint but needs kernel access and tracing tools | Understand security boundary, mode switches, syscall overhead 📊 | Systems, security engineering, low-level performance work 💡 | Explains safe OS interactions and syscall costs ⭐ |
| Describe different CPU scheduling algorithms and their trade-offs | Medium–High, multiple algorithms and metric analysis 🔄 | Requires traces/simulators and analytical tooling | Ability to evaluate fairness, throughput, latency trade-offs 📊 | OS design, scheduler tuning, cloud infra performance 💡 | Improves responsiveness and resource utilization ⭐ |
| What is virtual memory and how does paging/segmentation work? | High, hardware + OS interplay, page tables, TLBs 🔄 | Needs architecture docs, profilers, memory-heavy examples ⚡ | Understanding of page faults, thrashing, and protection mechanisms 📊 | Systems programming, DB internals, performance engineering 💡 | Explains isolation and efficient address space management ⭐ |
| Explain the OSI model and network layers with examples | Low–Medium, conceptual layering; mappings vary | Network tools (tcpdump, Wireshark) for practical demos ⚡ | Structured troubleshooting and protocol-to-layer mapping 📊 | Network engineering, DevOps, backend services 💡 | Provides a clear mental model for network problems ⭐ |
| What is a race condition and how do you prevent it? | Medium, conceptually simple, debugging can be hard 🔄 | Requires concurrency testing tools (ThreadSanitizer) and profilers | Ability to identify, reproduce, and mitigate concurrency bugs 📊 | Multithreaded apps, backend, systems programming 💡 | Ensures correctness and reliability under concurrency ⭐ |
| Explain process synchronization primitives and their use cases | High, many primitives and subtle semantics 🔄 | Needs threading libraries, runtime support, and tests | Design of correct and performant synchronization schemes 📊 | Databases, concurrent services, infrastructure systems 💡 | Complete toolkit for safe concurrent designs ⭐ |
| What is a semaphore and how does it differ from a mutex? | Low–Medium, focused conceptual comparison | Basic threading APIs; demos with counters/locks ⚡ | Correct selection between counting vs exclusive control 📊 | Embedded systems, connection pools, producer-consumer patterns 💡 | Clarifies counting (semaphore) vs exclusive (mutex) semantics ⭐ |
| Explain the concept of deadlock and how to prevent it | Medium, theory (4 conditions) + practical strategies 🔄 | Design practices, detection tools (graph analysis), timeouts | Ability to prevent, detect, and resolve indefinite blocking 📊 | Databases, distributed systems, multithreaded applications 💡 | Improves system robustness by eliminating circular waits ⭐ |
| Describe file system architecture and inode-based storage | High, many implementation variants and low-level detail 🔄 | Disk tools, fsck, storage hardware; test environments ⚡ | Understanding metadata, allocation, journaling, and recovery 📊 | Storage systems, DB engines, OS internals 💡 | Optimizes persistence, reliability, and recovery ⭐ |
Turn Definitions Into Interview-Ready Explanations
Review these operating system interview questions in four passes. In the first pass, define each concept in one or two precise sentences. Avoid hiding uncertainty behind jargon. If you can't explain a process, page fault, semaphore, or inode without repeating a textbook phrase, the definition needs more work.
In the second pass, trace a concrete execution or failure scenario. Draw a process and its threads, then follow a system call across the user and kernel boundary. Create a scheduling timeline and mark waiting and response behavior. For virtual memory, label the virtual page, TLB lookup, page-table entry, physical frame, and page-fault path. For concurrency, write the thread interleaving that produces a lost update. For storage, trace a path through directory entries to an inode and its data blocks.
The third pass is comparison. Explain why a process might be preferable to a thread, why Round Robin might fit interactive work better than FCFS, why paging avoids some fragmentation problems associated with segmentation, and why a semaphore expresses resource capacity while a mutex expresses exclusive ownership. Interviewers often use follow-up questions to test whether you understand the boundary of a choice. A candidate who can state both the benefit and the cost sounds more credible than someone who calls one design universally “best.”
The fourth pass connects each concept to debugging or system design. A system-call question can lead to buffering, tracing, or sandboxing. A scheduling question can lead to latency and starvation. A virtual-memory question can lead to TLB misses, page faults, and thrashing. A race-condition question can lead to stress testing, ThreadSanitizer, atomic operations, or lock design. A file-system question can lead to crash recovery, link behavior, and allocation decisions.
The historical development of operating systems helps explain why these subjects remain central. Unix began as an experiment at Bell Labs in 1970 on a PDP-7, was ported to the PDP-11, and was rewritten in C, milestones associated with portability and later influence across operating systems Unix history and operating-system milestones. Those ideas still shape the abstractions you discuss in interviews: processes execute programs, schedulers share hardware, virtual memory protects address spaces, and file systems organize persistent data.
Preparation should also match the role. General software-engineering interviews usually emphasize foundations, while infrastructure, backend, database, browser, embedded, and other performance-sensitive roles can require deeper reasoning about implementation and failure modes role coverage for operating-system interviews. A structured guide groups preparation around processes and threads, memory, scheduling, synchronization, deadlocks, and failure analysis, with trace-level tasks such as TLB behavior, demand paging, copy-on-write, and scheduling trade-offs structured operating-system interview preparation.
Keep your practice active. Draw scheduling timelines, address-translation flows, lock graphs, and inode relationships. Rehearse each answer aloud in a timed mock session, then ask yourself one follow-up question that changes the workload or failure condition. Interview Pilot's Question Bank, AI Mock Interview sessions, and adjustable Copilot depth can provide structure, but they shouldn't replace your own diagrams, traces, and explanations.
Recent preparation resources reflect that candidates increasingly want broader and more structured coverage. One resource organizes 130 operating-system topics across 14 modules, another uses 239 knowledge-check questions, and another states a total of 10,000 interview questions across role types structured operating-system study coverage. Use those resources as maps, not as substitutes for understanding. The most useful preparation is the ability to move from definition to mechanism, from mechanism to trade-off, and from trade-off to a decision you can defend.
Interview Pilot offers a searchable Question Bank, AI Mock Interview sessions, and Copilot controls for adjusting response depth while you practice operating system interview questions. Build your own traces first, then use Interview Pilot to rehearse role-specific follow-ups and explain each concept under interview conditions.
Topics
operating system interview questions
OS interview questions
operating systems
technical interview prep
systems programming
Continue reading
Interviews
10 Technical Interview Questions for Mechanical Engineering
Master technical interview questions for mechanical engineering with worked answers, calculation methods, and practical problem walkthroughs.
September 16, 2026
23 min read
Interviews
25 Common Technical Interview Questions and Answers (2026)
A practical 2026 guide to technical interview questions and answers, with sample responses for coding, systems, data, and IT screens.
August 10, 2026
14 min read
Interviews
10 Interview Questions on Microservices with Answers
Master interview questions on microservices with model answers, follow-ups, difficulty tags, and practice prompts for architecture and engineering roles.
September 24, 2026
21 min read