




Interviews
10 Interview Questions on Microservices with Answers
Master interview questions on microservices with model answers, follow-ups, difficulty tags, and practice prompts for architecture and engineering roles.
Interview Pilot Editorial Team
Updated September 24, 2026
21 min read
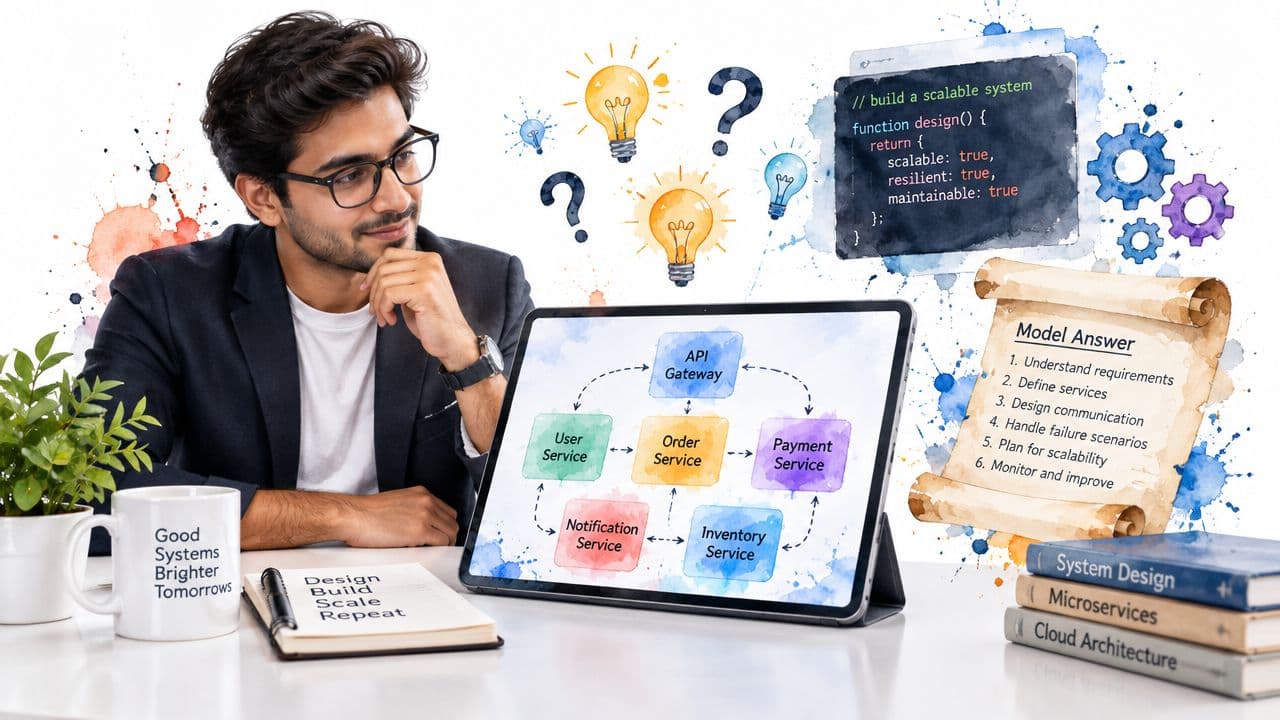
You're in a microservices interview, and the questions move beyond definitions almost immediately. The interviewer asks whether checkout should use REST, gRPC, or messaging, then probes how you'd preserve consistency when payment and inventory use separate databases. Before you finish, a dependency starts timing out in your design, and you need to explain how the system avoids a wider production failure.
Knowing what a microservice is won't carry that conversation. Strong answers show engineering judgment. They make a clear recommendation, explain the trade-off, and account for failure, delivery, and verification. That matters because microservices are now a common architectural choice rather than a niche topic. One industry report says about 74% of organizations globally use microservices architecture, while over 85% of large enterprises have deployed microservices in production (industry market report).
The ten interview questions on microservices below follow a practical progression, from architecture fundamentals through design, resilience, delivery, observability, incident response, and testing. Every item includes what the interviewer is testing, a model-answer direction, likely follow-ups, a difficulty tag, and a focused practice task.
Strong candidates don't present microservices as universally superior to a monolith. They explain when independent deployment and service ownership justify distributed-system complexity, and when they don't.
1. What Are Microservices and How Do They Differ from Monolithic Architecture?
Difficulty: Foundational
A microservices architecture organizes an application as a set of independently deployable services. Each service usually owns a business capability, exposes an explicit interface, and can evolve without rebuilding the entire application. A monolith packages those capabilities into one deployable unit, often with tighter coupling between modules and a shared data model.
A concise answer should compare the architectures across deployment, scaling, ownership, and failure behavior. A team might deploy an order service without releasing catalog code, or scale inventory separately from user profiles. That flexibility can support clearer ownership, but network calls, separate data stores, operational tooling, and distributed debugging become part of the system.
Practical rule: Don't describe microservices as “small classes deployed separately.” Service boundaries should reflect business responsibilities and data ownership, not arbitrary code size.
A strong candidate also states the cost. Independent deployment doesn't remove coordination. It replaces some in-process complexity with API compatibility, data consistency, service discovery, observability, and incident-management work. A modular monolith may be the better starting point when the domain is unclear, the team is small, or operational maturity is limited.
For broader software-engineering preparation, the software engineer interview guide can help you rehearse adjacent architecture and backend topics. For teams that need traceable controls around change and ownership, this microservices guide for audit-ready teams provides useful architectural context.
Likely follow-ups
- How would you identify a service boundary?
- Why might each service own its database?
- When would you reject microservices?
- How would you handle a cross-service business transaction?
Practice task: Compare a monolithic checkout system with a service-based design. Give one benefit, one operational cost, and one reason to keep the monolith.
2. Design a Microservices Architecture for an E-commerce Platform
Difficulty: Senior
Start with business capabilities, not infrastructure. A reasonable design might separate identity, catalog, cart, order, payment, inventory, fulfillment, and notification responsibilities. The API gateway can provide a client-facing entry point, authentication integration, routing, and request shaping, but it shouldn't become a hidden business-logic monolith.
Draw the critical flow aloud. A customer submits an order, the order service records an order intent, inventory reserves stock, payment authorizes funds, and fulfillment begins after the required events are available. Use synchronous calls where the caller needs an immediate decision, such as validating an authenticated request. Use asynchronous events where work can complete later, such as sending notifications or updating recommendations.
Every service should own the data required for its responsibility. Avoid direct database queries across service boundaries, because that creates hidden coupling and makes independent evolution difficult. For consistency, define what “confirmed order” means. If payment succeeds but inventory reservation fails, the design needs a compensating action, not a vague promise that the system will “roll back.”
A strong system-design response also includes operational foundations: timeouts, idempotency keys, retries, dead-letter handling, health checks, structured logs, metrics, and distributed tracing. Containerization with Docker and orchestration through Kubernetes may support deployment, but naming tools isn't a substitute for explaining behavior.
Use the system design templates to practice presenting boundaries, dependencies, and failure paths in a consistent order.
Likely follow-ups
- What happens when payment succeeds but inventory is unavailable?
- Which calls are synchronous?
- How do you prevent duplicate orders?
- Where do you place authorization and rate limiting?
Practice task: Sketch the order flow and annotate every service call as synchronous or asynchronous. Add one failure path for payment and one for inventory.
3. How Would You Handle Data Consistency Across Microservices?
Difficulty: Senior
The first sentence should establish the central constraint: services with independent databases can't rely on one local ACID transaction to protect a business process. The design must define which facts need immediate consistency, which can become consistent later, and how the system detects and repairs incomplete workflows.
For an order involving payment and inventory, a Saga is a practical answer. In an orchestration-based saga, a coordinator directs each step and triggers compensating actions when a later step fails. In a choreography-based saga, services react to events and publish their own outcomes. Orchestration gives you a clearer process view, while choreography reduces central coordination but can become difficult to reason about as event relationships grow.
Idempotency is essential. If a message or command is delivered again, processing it should not charge a customer twice or reserve the same stock repeatedly. Store an idempotency key or processed-event record, and make state transitions explicit. An outbox pattern can help ensure that a database change and the event describing it aren't published independently.
Avoid saying “use distributed transactions” as your default. Two-phase commit may be appropriate in constrained environments, but it increases coordination and availability costs. Event sourcing can provide an immutable history of state changes, yet it also introduces projection, schema-evolution, and operational complexity.
Likely follow-ups
- How do orchestration and choreography differ?
- What compensation reverses a successful payment?
- How do you handle an event that arrives twice?
- How do you monitor stuck sagas?
Practice task: Write the state transitions for an order from Pending through payment failure, inventory failure, and successful fulfillment. Include the event or command that causes each transition.
4. Scenario: Your Payment Service Is Down. How Would Your Microservices System Handle This?
Difficulty: Advanced
Don't begin by retrying every failed request. First decide whether the payment dependency is unavailable, slow, returning a known business rejection, or returning an ambiguous result. A timeout must not automatically mean that payment failed, because the provider may have accepted the charge before the response was lost.
Use a circuit breaker to stop sending requests to a dependency that is repeatedly failing. Set bounded timeouts, then apply retries only to errors that are plausibly transient. Exponential backoff with jitter prevents a large group of clients from retrying simultaneously when the provider recovers.
A bulkhead can isolate payment resource usage from unrelated order operations. For a business that permits delayed confirmation, the order service can create a pending order, place a payment command on a durable queue, and expose a status that clearly says confirmation is still processing. That path requires idempotency, reconciliation, and customer communication.
Don't let the fallback create a false success. “Order received, payment pending” is safer than “Order confirmed” when authorization hasn't completed. Operations should receive alerts based on payment error rates, circuit state, queue age, and reconciliation gaps.
Likely follow-ups
- What if the payment request timed out after authorization?
- Which errors are safe to retry?
- How does the customer learn the final result?
- How do you prevent a payment retry from charging twice?
Practice task: Design a payment state machine with Pending, Authorized, Declined, Unknown, and Reconciled states. Explain how the system handles the Unknown state.
5. What Communication Patterns Would You Use Between Microservices and When?
Difficulty: Intermediate
Choose communication based on business timing, coupling, failure tolerance, and payload shape. REST is often a practical choice for broad compatibility and human-readable APIs. gRPC can work well for internal, strongly typed, low-latency communication, especially when streaming or generated clients matter. Both are synchronous, so callers wait for a response and must handle dependency latency.
Messaging is a better fit when the producer shouldn't wait for every consumer. An order-created event might update analytics, trigger notifications, and start fulfillment independently. Kafka supports durable event streams and replay-oriented workflows, while RabbitMQ can suit task queues and routing patterns. The tool matters less than the delivery contract.
Synchronous calls are useful when the caller needs a decision before continuing, such as validating a request or authorizing a payment. Asynchronous messaging is useful for notifications, indexing, and workflows that tolerate delay. The trade-off is real: asynchronous designs reduce direct coupling but add eventual consistency, schema evolution, duplicate delivery, ordering, poison messages, and harder debugging.
State your failure policy. Every consumer needs retry rules, dead-letter handling, idempotent processing, and observability. Don't claim that asynchronous communication automatically makes a system more scalable or reliable. It moves failure management into queues, consumers, and operational workflows.
Likely follow-ups
- How do you preserve ordering?
- What happens when a consumer is offline?
- When would you choose REST over gRPC?
- How do you evolve an event schema?
Practice task: Choose a communication pattern for checkout, email notifications, inventory reservation, and analytics. Defend each choice in one sentence.
6. How Would You Handle Service Discovery in a Microservices Environment?
Difficulty: Intermediate
Service discovery lets a service find healthy instances without hard-coding changing addresses. In a container platform, instances can be replaced, rescheduled, or scaled, so a stable logical name should resolve to currently available endpoints.
There are two common models. With client-side discovery, the caller queries a registry and selects an instance. This gives the client control over load balancing but spreads discovery logic across languages and services. With server-side discovery, the caller sends traffic to a load balancer or proxy, which resolves and routes the request. Clients stay simpler, but the routing layer becomes an important dependency.
Kubernetes provides service names and DNS-based discovery inside the cluster. Consul and Eureka represent registry-oriented approaches. Whichever model you choose, discovery must be connected to health information. A process that accepts TCP connections but can't reach its database may be alive without being ready for traffic.
Also discuss security. Service discovery isn't authorization. Use network policies, service identities, and mutual TLS or an equivalent control where appropriate. Load balancing may use round-robin, least connections, or another strategy based on request characteristics.
Likely follow-ups
- What happens when the registry is unavailable?
- How do you remove unhealthy instances?
- How do services authenticate to one another?
- Why might DNS caching cause stale routing?
Practice task: Explain how an order service discovers inventory instances in Kubernetes. Include readiness checks and the behavior during a rolling deployment.
7. Scenario: You Need to Deploy a New Version of a Microservice Without Downtime. How Would You Approach This?
Difficulty: Advanced
Begin with compatibility. A deployment strategy can't compensate for an API or database migration that breaks the version still serving traffic. Make the new service version tolerate the old request and response shape, deploy additive database changes first, and remove obsolete fields only after all consumers have migrated.
A rolling update replaces instances gradually and can be the simplest option when health checks and backward compatibility are strong. A blue-green deployment runs two environments and shifts traffic between them, which simplifies rollback but consumes additional capacity and still requires careful database handling.
A canary release sends a controlled portion of traffic to the new version while you compare error rates, latency, saturation, business outcomes, and logs. It offers realistic feedback before broad rollout, but it demands good observability and a reliable traffic-shifting mechanism. Feature flags separate code deployment from feature activation, which helps teams disable behavior without rebuilding the service.
A successful deployment isn't just “the pods are running.” It's a release with a rollback decision, compatibility plan, and evidence that customer behavior remains healthy.
Automate rollback conditions, but keep human judgment for ambiguous business failures. A service can pass infrastructure health checks while producing incorrect invoices or accepting invalid orders.
For related release and operations practice, review these DevOps interview questions.
Likely follow-ups
- How would you roll back a database migration?
- Which metrics decide whether a canary proceeds?
- How do you handle long-running requests?
- What if old and new versions publish different events?
Practice task: Describe a canary plan for a pricing service. Name the compatibility requirement, the signals you would watch, and the rollback trigger.
8. How Would You Implement Logging, Monitoring, and Tracing Across Microservices?
Difficulty: Advanced
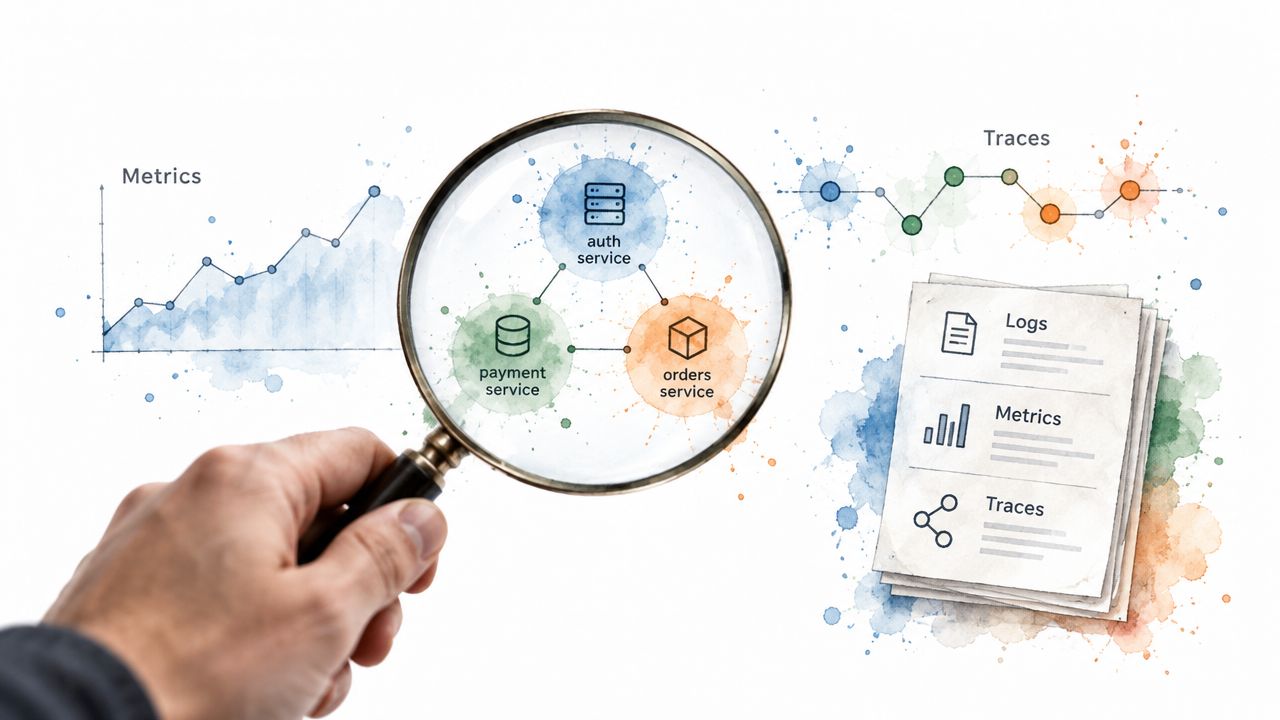
Distributed systems need three complementary views. Logs record detailed events, metrics summarize behavior over time, and traces connect one request across service boundaries. None is sufficient alone. A log may show an error without its upstream cause, while a metric may show rising latency without identifying the slow dependency.
Propagate a correlation or trace ID through HTTP requests and messages. Use structured JSON logs with fields such as service name, environment, operation, request ID, outcome, and duration. Never put credentials, payment secrets, or unnecessary personal data into logs.
Track service-level signals that help operators make decisions: request volume, error rate, latency distributions, saturation, queue age, dependency failures, and circuit-breaker state. Distributed traces should show the time spent at each hop, including database and external-provider spans. OpenTelemetry can provide a common instrumentation and export approach, with systems such as Prometheus, Jaeger, or Elastic used for storage and analysis.
Alert on symptoms that affect users or threaten recovery, not every unusual event. High-cardinality labels and unbounded log volume can make observability expensive and noisy, so sampling and retention policies need deliberate design.
A useful implementation diagram belongs after you explain the signals:
Likely follow-ups
- How do you trace an asynchronous message?
- Which alerts page an engineer?
- How do you reduce noisy logs?
- What would you check when latency rises but errors don't?
Practice task: Define the log fields, metrics, and trace spans for an order request that calls inventory and payment.
9. Scenario: Your Microservices System Is Experiencing Cascading Failures. Diagnose and Fix This.
Difficulty: Expert
Treat the incident as a dependency graph, not a collection of isolated errors. Start with the timeline. Identify which service first became slow or unavailable, then examine upstream timeouts, retry volume, queue growth, thread or connection exhaustion, and shared-resource contention.
A common cascade looks like this: a dependency slows down, callers wait until timeout, retries increase load, worker pools fill, queues grow, and services that were healthy begin timing out. Tracing helps reveal the first degraded span, while metrics show whether the system is failing through errors, saturation, or latency.
Containment comes before architectural cleanup. Stop nonessential traffic, reduce retry pressure, open circuit breakers, isolate workloads with bulkheads, and apply backpressure where queues or consumers are overloaded. Graceful degradation may mean returning cached data, disabling recommendations, or accepting an operation for later processing. Increasing timeouts indiscriminately usually makes the incident worse by holding resources longer.
After stabilization, identify the trigger and the amplifier. The trigger might be a dependency outage, capacity problem, deployment defect, or configuration error. The amplifier might be unbounded retries, a shared connection pool, missing limits, or insufficient isolation. Add a regression test, capacity guard, alert, or game-day scenario that addresses the mechanism, not just the specific incident.
“Retry” isn't a resilience strategy unless the system controls timing, volume, eligibility, and total work.
Likely follow-ups
- How do you locate the first failing dependency?
- What does a circuit breaker protect?
- When is graceful degradation unsafe?
- How would you test the fix?
Practice task: Given a slow payment provider, list three immediate containment actions and three long-term changes. Explain which one reduces load first.
10. What Are the Testing Challenges in Microservices and How Would You Address Them?
Difficulty: Advanced
Testing microservices is difficult because correctness exists at several levels. A service can pass unit tests while violating an API contract, mishandling duplicate messages, or failing when a dependency times out. The answer should show how the test strategy covers both local logic and distributed behavior.
Use fast unit tests for domain rules and deterministic transformations. Use integration tests to verify database behavior, serialization, authentication, and service wiring against realistic dependencies. Contract tests are particularly valuable when teams deploy independently. A consumer describes the interaction it requires, and the provider verifies that it still satisfies that contract.
End-to-end tests should cover a small set of critical user journeys, such as placing an order and confirming payment. They're slower and more environment-sensitive, so don't use them to test every validation rule. Test asynchronous behavior explicitly: duplicate events, out-of-order delivery where relevant, poison messages, retries, dead-letter processing, and replay.
Test data ownership needs equal attention. Avoid a shared mutable fixture that makes failures order-dependent. Build data per scenario, clean it reliably, and make event assertions tolerant of legitimate processing delay without hiding real failures.
Production safeguards complement pre-release testing. Health probes, dashboards, gradual releases, and controlled fault injection can expose failure modes that a clean test environment misses. The right question isn't whether a service has tests. It's whether the team can demonstrate compatibility, recoverability, and correctness at each boundary.
Likely follow-ups
- When would you use contract tests instead of end-to-end tests?
- How do you test eventual consistency?
- How do you prevent flaky asynchronous tests?
- What failure would you simulate in production-like testing?
Practice task: Create a test matrix for order creation. Include unit, integration, contract, end-to-end, and failure-path cases.
Comparison of 10 Microservices Interview Questions
| Item | Complexity 🔄 | Resources & Effort ⚡ | Expected outcomes ⭐📊 | Ideal use cases | Key advantages 💡 |
|---|---|---|---|---|---|
| What are Microservices and How Do They Differ from Monolithic Architecture? | Low, conceptual; tests fundamentals | Low, interview question, no infra | ⭐⭐, reveals architectural thinking and terminology | Screening for architects/software engineers | Clear discriminator between modern vs legacy knowledge; easy to illustrate with examples |
| Design a Microservices Architecture for an E-commerce Platform | High, open-ended system design | High, whiteboard + time; may require diagrams | ⭐⭐⭐, demonstrates design, trade-offs, scalability plans | Senior engineers, solutions architects, tech leads | Comprehensive view of service boundaries, data, comms, and ops considerations |
| How Would You Handle Data Consistency Across Microservices? | High, theoretical + practical patterns | Medium, conceptual; examples of Sagas/eventing expected | ⭐⭐⭐, assesses deep distributed-systems knowledge | Finance, e‑commerce, consistency‑critical systems | Differentiates candidates familiar with CAP, Sagas, event sourcing, compensations |
| Scenario: Your Payment Service is Down. How Would Your Microservices System Handle This? | Medium, scenario-based resilience problem | Medium, requires runbook/operational thinking | ⭐⭐, reveals fault‑tolerance and mitigation strategies | Roles focused on reliability, SRE, DevOps | Tests circuit breakers, bulkheads, async fallbacks and graceful degradation |
| What Communication Patterns Would You Use Between Microservices and When? | Medium, comparative design question | Medium, expects protocol knowledge (REST/gRPC/Kafka) | ⭐⭐, shows trade‑off decisions for latency, coupling | Backend architects, data engineers, system designers | Illuminates when to use sync vs async, ordering, durability, and broker choices |
| How Would You Handle Service Discovery in a Microservices Environment? | Medium, design + platform specifics | Medium, knowledge of tools (K8s, Consul, Eureka) | ⭐⭐, assesses cloud‑native and orchestration familiarity | DevOps, cloud architects, SREs | Evaluates client‑ vs server‑side discovery, health checks, load balancing |
| Scenario: Deploy a New Version of a Microservice Without Downtime | Medium, operational strategy question | Medium, CI/CD, deployment strategy knowledge | ⭐⭐⭐, shows release risk mitigation and rollback plans | DevOps, SREs, release engineers, tech leads | Tests blue/green, canary, rolling updates, feature flags, DB migration planning |
| How Would You Implement Logging, Monitoring, and Tracing Across Microservices? | Medium‑High, observability design | High, requires tooling and costs awareness | ⭐⭐⭐, critical for operability and debugging | SREs, DevOps, backend engineers | Covers logs/metrics/traces, correlation IDs, sampling and alerting strategies |
| Scenario: Your Microservices System is Experiencing Cascading Failures. Diagnose and Fix This. | Very High, complex incident response | High, needs systems thinking and tracing data | ⭐⭐⭐, differentiates senior incident‑handling and architecture skills | Senior engineers, SREs, incident managers | Tests root cause analysis, backpressure, circuit breakers, bulkheads and mitigation steps |
| What Are the Testing Challenges in Microservices and How Would You Address Them? | Medium, testing strategy + trade‑offs | Medium, knowledge of contract/integration testing | ⭐⭐, evaluates QA approach across distributed systems | QA, backend engineers, tech leads | Emphasizes testing pyramid, contract testing, flakiness mitigation and test environments |
Turn Each Question Into a Rehearsal Plan
Reading model answers creates recognition, not fluency. In an interview, you need to make a decision while the interviewer changes the constraints. Practice each question until you can answer it without reciting a prepared paragraph.
Use four layers for every response:
- Give the decision or definition first. State what microservices are, choose REST or messaging, or explain that a circuit breaker limits calls to a failing dependency.
- Explain the trade-off. Mention coupling, latency, consistency, operational cost, rollback complexity, or test reliability.
- Add a concrete scenario. Use checkout, payment authorization, inventory reservation, deployment, or an incident timeline.
- Finish with a safeguard. Name idempotency, timeouts, compensation, health checks, tracing, contract tests, or a rollback plan.
This structure keeps answers concise while showing depth. It also prevents a common weak pattern, saying “it depends” without explaining what changes the decision. State your default, then identify the condition that would make you choose differently.
Follow-up questions deserve separate rehearsal. After answering about asynchronous messaging, expect questions about duplicate delivery, ordering, schema evolution, or dead-letter queues. After discussing deployment, expect questions about database compatibility, rollback, and old clients. Record yourself answering, then remove tool names that aren't connected to a design decision.
Adapt examples to the role. A backend candidate can emphasize API contracts, data ownership, and failure handling. An SRE-oriented candidate should foreground saturation, alert quality, recovery objectives, and incident containment. A platform candidate may need to explain service discovery, deployment automation, security boundaries, and developer experience.
Mock interviews are useful because they force you to handle interruptions and changing assumptions. Interview Pilot offers guided mock interview sessions and a searchable bank of common questions, including software-engineering preparation. It can support rehearsal, but it shouldn't replace understanding why a design works, where it fails, and what evidence would validate it.
Before the interview, review your answers for clarity rather than memorized terminology. Can you state the recommendation in one sentence? Can you explain the main cost in another? Can you describe one failure and one operational safeguard without drifting into unrelated implementation detail? If so, you're demonstrating the judgment interviewers are looking for.
Use Interview Pilot to rehearse microservices scenarios with guided mock interviews and searchable technical questions. Practice explaining service boundaries, consistency, resilience, deployment, and testing aloud, then refine each answer around a clear decision and trade-off.
Topics
interview questions on microservices
microservices interview
system design interview
distributed systems
software engineering interview
Continue reading
Interviews
10 Operating System Interview Questions
Prepare with 10 operating system interview questions covering processes, memory, concurrency, file systems, model answers, and study resources.
September 24, 2026
24 min read
Interviews
8 Embedded Systems Interview Questions
Prepare for embedded systems interview questions with sample answers on MCUs, RTOS, interrupts, memory, bootloaders, debugging, and design.
September 23, 2026
20 min read
Interviews
10 Excel Interview Questions by Skill Level
Prepare with 10 Excel interview questions by skill level, including formulas, tasks, pivot table exercises, and practical answer strategies.
September 22, 2026
23 min read